
Serverless MicroVM Benchmark: Cold-Start Telemetry vs. 5M Requests at 500 Concurrency
Most serverless benchmarks either mix cold starts into steady-state percentiles or obscure what is actually happening inside the host orchestrator versus inside the guest VM.
To obtain an honest, reproducible look at both wake-up overhead and raw sustained throughput, we ran a two-phase benchmark across four backend JavaScript runtimes (Fairyfly (ff), Bun, Deno, and Node.js) running inside isolated microVMs configured with:
- 2 vCPUs
- 1 GB RAM
- Linux kernel with container/microVM hypervisor isolation
The benchmark was executed in two decoupled phases:
- Phase 1 (Isolated Cold Start): A single first request executed prior to load generation to dissect the exact host orchestrator overhead, network phases, and inside-VM application initialization time to bind and listen on the port.
- Phase 2 (High-Concurrency Load): 5,000,000 requests across 500 concurrent connections via
ohato measure maximum sustained throughput (RPS) and full tail latency distribution (p10 to p99.9).
Phase 1: Isolated Cold-Start Breakdown
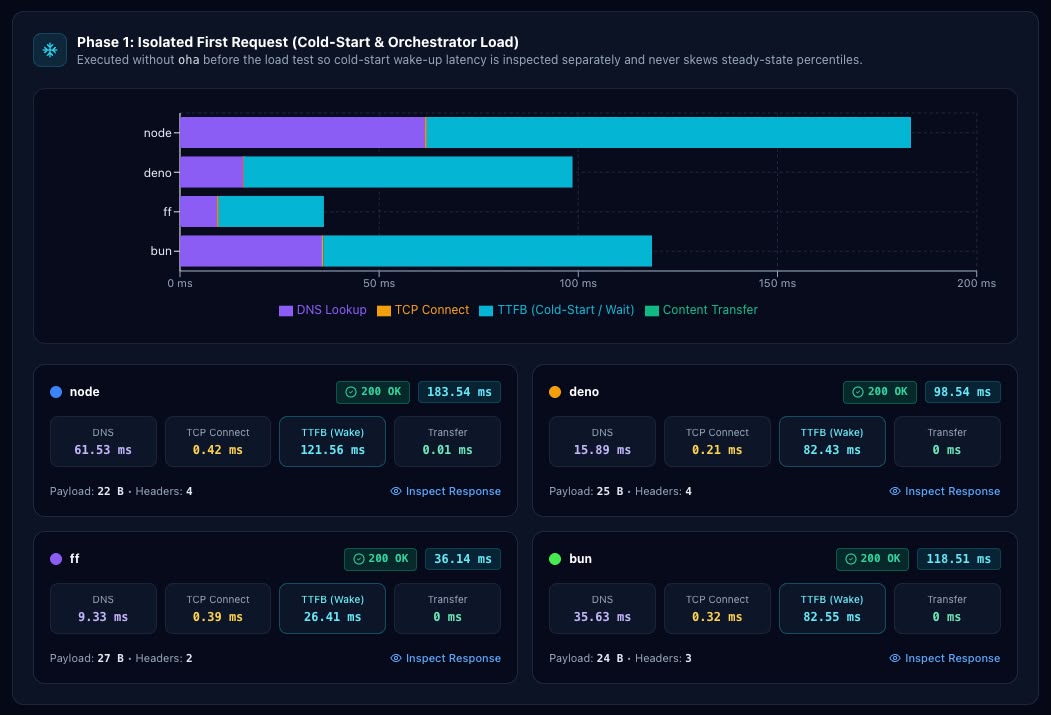
When benchmarking serverless cold starts, reporting only end-to-end (E2E) time hides whether latency came from DNS resolution, host hypervisor dispatch, or the runtime bootstrapping its JavaScript engine.
Here is the exact telemetry for the first request:
Key Cold-Start Insights
- ~10 ms App Cold Start: Inside the microVM, Fairyfly takes just 10.4 ms to boot QuickJS, parse the handler, and bind its 512-slot HTTP listener to the port. That is ~8x faster than Bun (80.5 ms) and Deno (79.4 ms), and over 11x faster than Node (118.6 ms).
- Sub-30ms Total Internal Wake: Even with 16 ms of host orchestrator handoff tax, Fairyfly's total TTFB was 26.41 ms.
- The V8 & JSC Bootstrap Tax: For Bun, Deno, and Node, host orchestration took only 2–3 ms; 96%–98% of their entire wake latency was pure runtime initialization inside the VM (allocating isolate heaps, loading snapshot blobs, and bootstrapping C++ runtime shims).
Phase 2: Warm High-Concurrency Stress Test (5M Requests @ 500 Concurrency)
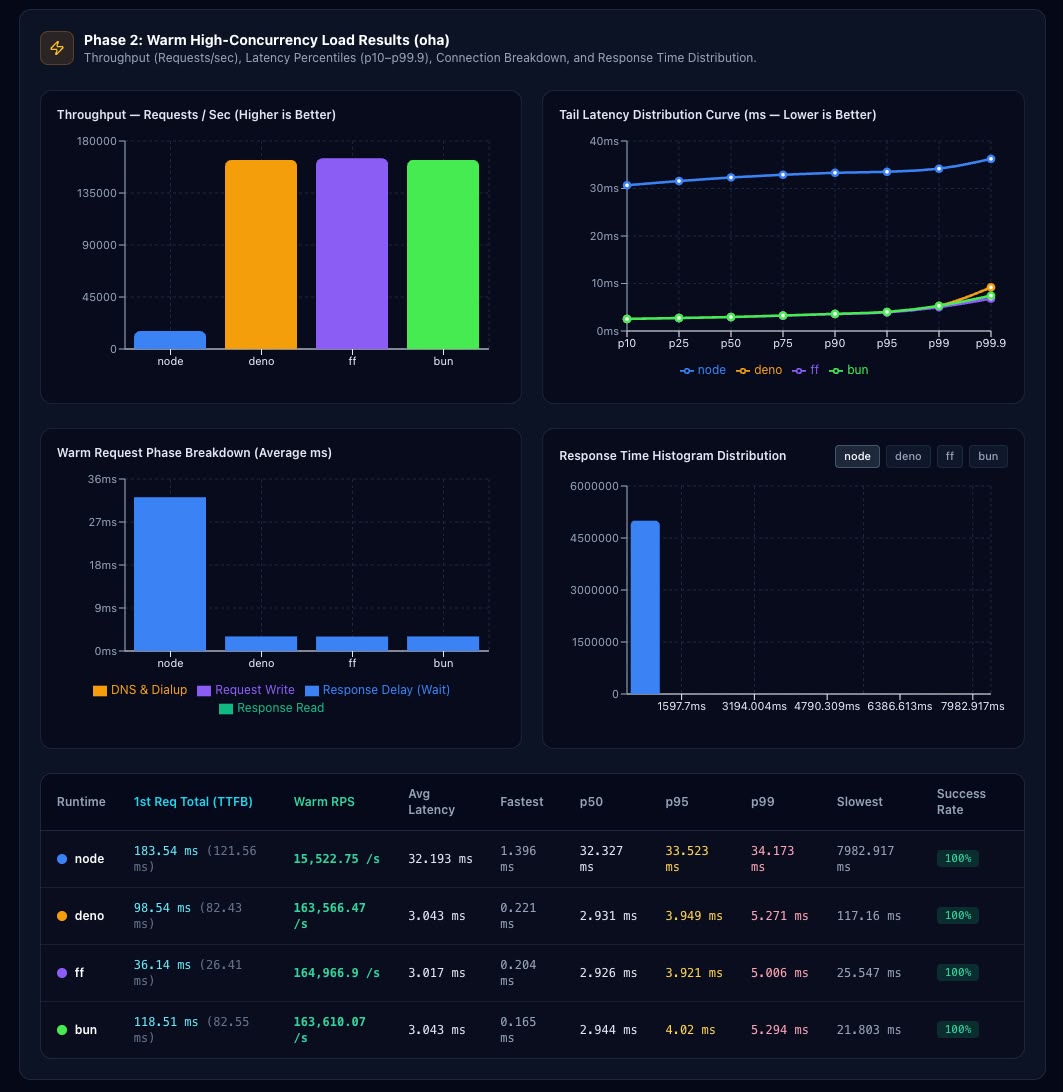
Once warm, we drove 5,000,000 HTTP requests across 500 concurrent connections using oha against the same 2 vCPU / 1 GB microVM instances.
Telemetry Summary
Analysis: Why the Numbers Look Like This
1. The I/O Dominance Effect
Conventional wisdom assumes that JIT-compiled engines (V8 in Node/Deno, JavaScriptCore in Bun) must always beat interpreted engines (QuickJS in Fairyfly) on raw requests per second.
In real-world network services, this assumption fails. When processing high-concurrency HTTP:
- Handlers spend the vast majority of CPU cycles in kernel context switches, socket readiness notification, header framing, and memory copies.
- Fairyfly's networking engine is written in native Zig with libxev (
io_uring/kqueue/epoll), a 512-slot Structure-of-Arrays (SoA) connection table, packed 2-byte connection flags, and refcounted header buffers. - Because the Zig layer handles the socket lifecycle and staging buffers with near-zero allocation, QuickJS only executes the tiny JavaScript callback. As a result,
ffachieves 164.9k RPS, matching or slightly edging out Bun (163.6k RPS) and Deno (163.5k RPS).
2. Tail Latency & Memory Pressure (The 1 GB RAM Bottleneck)
At 500 concurrent connections on a tight 1 GB RAM footprint:
- Node.js dropped to 15.5k RPS (10.6x slower). The combination of V8 heap allocations per connection, garbage collection compaction pauses, and event loop starvation resulted in average latencies of 32 ms and an extreme tail spike reaching 7,982 ms (~8 seconds).
- Deno sustained 163.5k RPS, but suffered a 117.16 ms outlier spike.
- Bun and Fairyfly demonstrated exceptional tail stability: Bun capped its worst request at 21.8 ms, and Fairyfly clamped at 25.5 ms, with p99 holding at 5.00 ms.
- All 5,000,000 requests finished with a 100% success rate (0 dropped requests) on Fairyfly.
Takeaways for Serverless Architecture
- True Scale-to-Zero is Now Viable: If guest runtime cold start is ~10 ms instead of ~80–120 ms, serverless platforms can scale down to 0 instances aggressively without sacrificing user perceived responsiveness on the first request.
- Dense Packing on Smaller VMs: On a 2 vCPU / 1 GB machine, Fairyfly can sustain over 160,000 requests/sec across 500 concurrent sockets right inside its 512-slot table without thrashing the allocator or running out of memory.
- Auditability Without Speed Penalty: You do not need a multi-million line C++ engine to achieve top-tier server throughput. A clean ~24k line Zig codebase with QuickJS can match or outperform the heaviest runtimes on the web.